How to Fix Flaky Tests in a CI Pipeline: A Step-by-Step Diagnosis
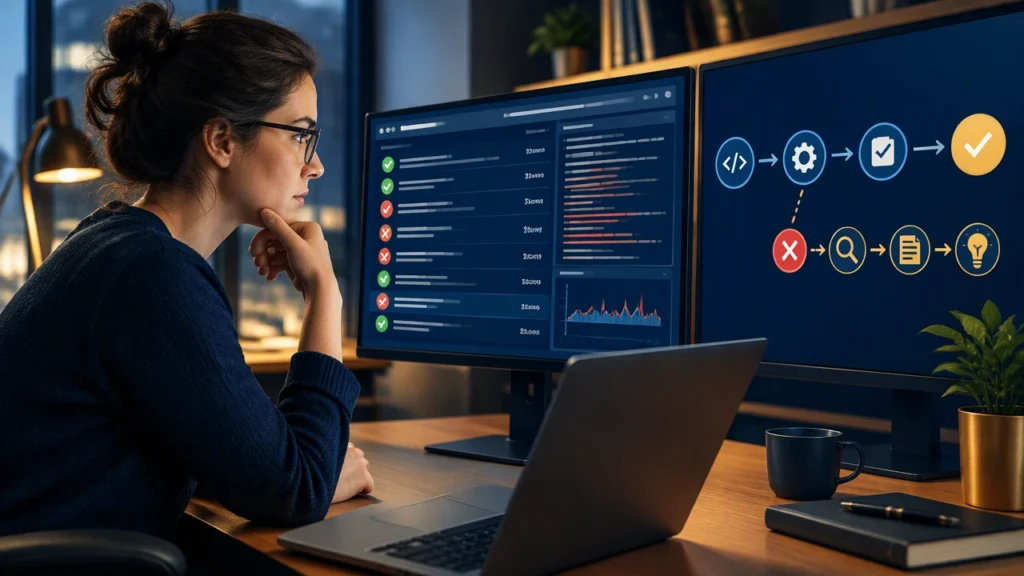
Intermittent failures are among the most expensive problems in software testing. A build passes on one run and fails on the next without a code change, so the team starts rerunning jobs, delaying releases, and questioning every red build. This guide explains how to fix flaky tests in a CI pipeline by diagnosing the cause before changing the test, then applying engineering fixes that make results repeatable.
Define the failure pattern before touching the test
Start with a short incident record. Capture the job URL, commit SHA, branch, runner type, timestamp, and the exact assertion or error message. Record whether the failure happens on pull requests, nightly builds, or both. This information separates a test problem from an infrastructure problem.
Look for patterns rather than isolated events:
- Does the test fail only on a specific runner, operating system, or browser?
- Does it fail after parallel workers increase?
- Does it fail when network services or databases are under load?
- Does it fail more often near a timeout boundary?
- Does rerunning the same commit change the result?
A useful first metric is the failure rate over the last 20 to 50 runs. A test that fails once in 40 runs still consumes attention and can block a release. Track the rate by environment so you can see whether the issue is concentrated in one lane.
Reproduce the failure under controlled conditions
Reproduction turns a vague complaint into an engineering task. Run the suspect test in isolation, then run it with the full suite. If it passes alone but fails in the suite, suspect shared state, resource contention, or ordering dependencies. If it fails alone, inspect the test logic and its external dependencies.
Repeat the run with the same seed or ordering when your framework supports it. Increase verbosity only enough to expose timing, retries, and cleanup. Save the logs as CI artifacts so failures can be compared later. Avoid adding random sleeps while investigating; they hide the race instead of proving it.
Classify the root cause
Most intermittent failures fall into a small number of categories. Naming the category makes the fix and the prevention work clearer.
Time and timing
Tests that assume an operation finishes immediately are vulnerable to slow CPUs, saturated runners, and garbage collection. Look for fixed waits, assertions checked before an event has propagated, and timeouts that are too close to normal latency. Replace arbitrary delays with explicit conditions: wait for a request to complete, a queue to drain, a file to appear, or a UI element to reach a stable state.
Shared state and ordering
Tests may depend on database rows, environment variables, files, caches, or global singletons created by an earlier test. A suite that passes in one order can fail in another. Prefer fresh fixtures per test, transactional cleanup, isolated namespaces, and unique identifiers. Make tests independent enough to run in any order and in parallel.
External systems and network behavior
Real services introduce latency, rate limits, DNS changes, and partial outages. Decide which tests need a real service and which do not. Keep contract tests close to the boundary, use deterministic test doubles for most logic, and reserve end-to-end tests for critical journeys. If a network call is required, set explicit timeouts, retry only idempotent operations, and make failures observable.
Test design and hidden assumptions
Some tests assert on wall-clock time, random values, unordered collections, or implementation details that change between builds. Make assertions deterministic. Compare sets when order is irrelevant, inject a clock, seed randomness, and assert behavior rather than private calls. Ensure cleanup runs even when an assertion fails.
Apply fixes in the smallest safe step
Fix the cause, not the symptom. A retry wrapper can reduce noise, but it can also hide a real race and extend feedback time. Use retries as a temporary guardrail while you investigate, then remove them when the underlying issue is resolved.
A practical sequence is:
- Repair the test’s synchronization or cleanup.
- Isolate shared resources and make ordering irrelevant.
- Reduce external dependencies or make them deterministic.
- Adjust timeouts based on measured latency, not intuition.
- Add a narrow retry only for an operation that is genuinely idempotent.
Keep each change in a separate commit when possible. That makes it easier to see which change lowered the failure rate and to revert a fix that introduces new instability.
Make the pipeline trustworthy again
Trust comes from visible, consistent signals. Quarantine a known flaky test so it does not block unrelated work, but keep it running in a scheduled job with an owner and a removal date. Report flaky tests as a first-class metric, including failure rate, mean time to detect, and time to repair.
Run high-risk suites with sensible parallelism, stable runner images, and pinned dependencies. Keep artifacts such as logs, screenshots, traces, and seed values for failed runs. Review changes to tests with the same care as production code, and require evidence that a fix reduces the failure rate.
Finally, hold a short blameless review when a pattern appears. Ask what the pipeline revealed about timing, isolation, or dependency management, then turn the answer into a checklist item for future tests. The goal is not a perfect suite on day one. The goal is a pipeline where a red build means something needs attention, and a green build can be believed.